Autonomous Follow-Up: The Leads Ace Autopilot Won’t Touch
Ace Autopilot works the contacts nobody on the team is working. Before it writes to anyone it has to clear a fixed list of checks: no agent active in the last week, not under contract, a consent basis on file, and something specific it can say out loud. Fail one and it declines, by name.
Two contacts in your Follow Up Boss account look identical in a report: quiet for eight months, tagged buyer, same assigned agent, same source. One is safe for software to email tomorrow morning. The other is under contract on a house and three days from closing.
No lead score separates those two. No dashboard column does either. And the cost of getting it wrong is not a low open rate. It is a client reading a re-engagement note about finding them a home while their file sits at the title company.
That is the actual problem in autonomous follow-up. Writing a decent message is close to solved. Deciding, with nobody in the room, which contacts to leave completely alone is not. Ace Autopilot — the part of Ace Trove that works the contacts nobody is working — spends most of its run deciding not to write.
Most of the job is the refusal
There is research behind that, though not from our industry. A 2025 meta-analytic review in the Journal of Advertising Research pooled 53 experimental studies and found personalized advertising generally more effective than generic advertising on overall persuasion, attitudes and behavioral intentions. The mechanism is the part worth sitting with: in the authors’ modelling it was perceived relevance, and not perceived intrusiveness, that explained why personalization persuaded (Yeo et al., 2025).
The shallow end is not nothing. In randomized field experiments with three companies across millions of recipients, adding the recipient’s name to a subject line raised the probability of an open from 9.05% to 10.80% and sales leads from 0.39% to 0.51% (Sahni, Wheeler and Chintagunta, 2018, Marketing Science). Neither study looked at real estate follow-up, and neither tested an AI writing on its own. They tell you which lever is long, not what your numbers will do.
Read together, they leave anything that sends on a schedule with an awkward question. A mail-merge first name buys a fraction of a percent. What carries the weight is relevance the recipient can actually feel — so what happens when you hold nothing relevant about them? A model asked to be specific with no specifics available will invent some. The only structural answer is to not send.
The list a contact has to clear
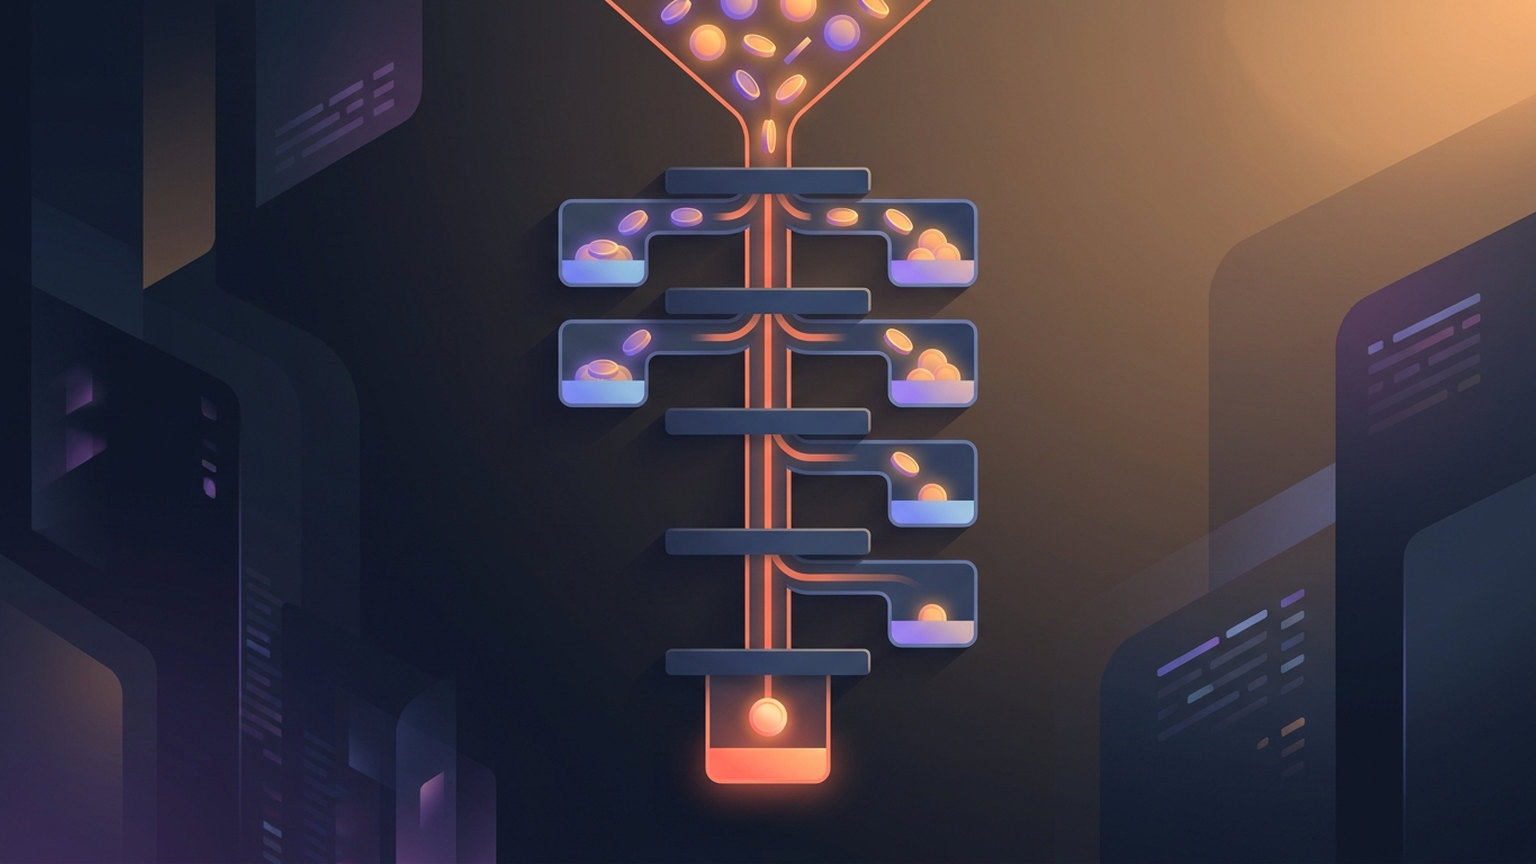
In plain English, in the order it runs:
| The check | What it stops |
|---|---|
| Is this person a prospect at all? | The lenders, recruiters, vendors and other agents in the same list as your buyers (not everyone in your database is a lead) |
| Do we know where they stand? | A contact whose lifecycle state can’t be derived is skipped, not guessed at |
| Are they under contract? | Deal work. A hard stop, and no shipped workflow lists that state |
| Has a human touched them in the last seven days? | Landing on top of a live thread. No score, tier or estimated value overrides it |
| Is the contact mid-conversation already? | Interrupting a thread the contact is actively in |
| Is another automation already talking to them? | Two systems working one human at once |
| Is there an assigned agent and a real way to reach them? | Outreach with no owner, no sender, or no deliverable address |
| Is there a consent basis? | A message with nothing behind it: either the contact’s own basis or your explicit tag enrollment |
| Has anyone opted out, anywhere? | A “no” recorded anywhere, including the partner texting platform’s tags |
| Is there a specific reason to write? | The generic drip. With the consent check above it, this is where most contacts stop |
| Is it too soon, or is the day’s budget spent? | Stacked touches and surprise blasts. The daily budget comes from your Trove volume tier and can be extended by purchase — never a number you type in |
Twenty-seven named refusal reasons sit in that closed list today, and every one that applies gets collected rather than the first short-circuiting the rest — so fixing one reason doesn’t surface a fresh one on the retry.
What it may say, and what only tells it when to write
That last check asks what most tools in this category never ask: does this message have a reason to exist?
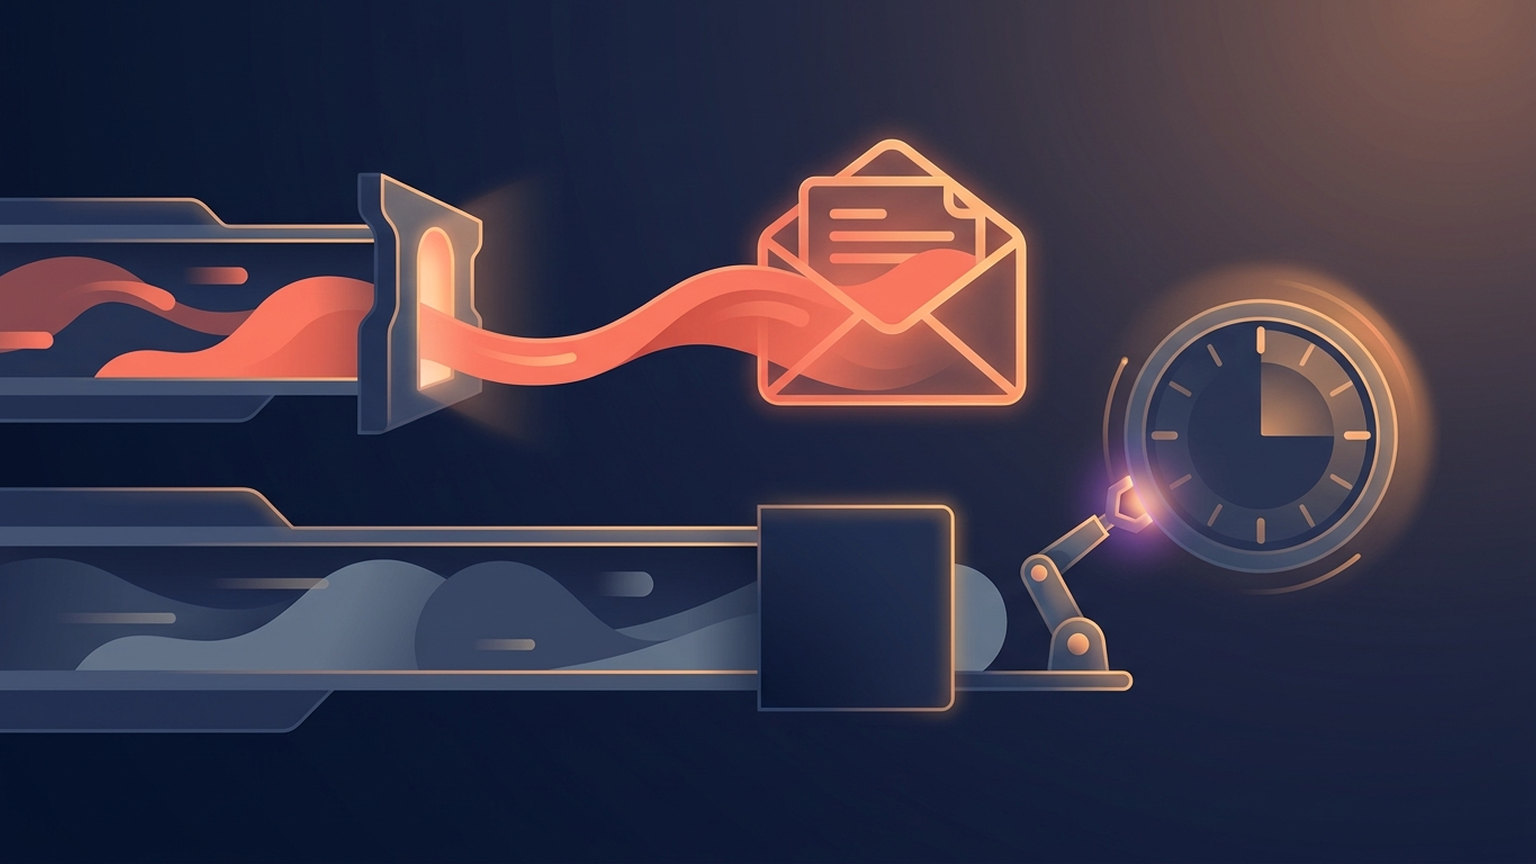
Evidence splits in two, and the side a fact lands on is fixed by the kind of fact it is, never decided per message.
Can appear in the message: how they first reached the agent, what they typed into a form themselves, who introduced them, a real message they sent, a fact the agent recorded about them.
Can only affect timing: property views, movement in a score or tier, modeled home equity, the agent’s commission math. These never reach the draft. They are stripped before the prompt is assembled and stripped again on the way out, by two separate filters, because the cost of one being edited wrong is an email telling a stranger we watched them browse houses. Two consequences follow:
- Age alone never earns a message. That someone inquired fourteen months ago is fair to mention, since they know it too. It still can’t be the reason for writing. Every contact in every database has an age; if age cleared the bar, everyone would clear it, and the generic drip would be back wearing a badge.
- It never explains how it knows. No “I saw you were looking at”, no “our records show”, no reciting a note back to the person it was written about. Something they said or wrote can be restated as theirs. A field in a CRM row becomes a question instead.
No probability, score, tier, commission figure or estimated property value is ever stated to a recipient. Those are internal numbers for deciding who to call, not things to say to the person being called.
Where the rest of the category is going
Fello announced Felix in May 2026: an agent that, per Inman’s coverage, calls, texts and emails leads autonomously, adapts its outreach as new data arrives, and hands qualified prospects to a human while the prospect is still on the line. Fello says consent is captured through its email platform before calls or texts begin, that the list is scrubbed against the Do Not Call registry, and that Felix discloses it is a digital assistant when asked (Inman, May 22, 2026; in beta with roughly 20 teams then — check current status with them).
That is a real product with published guardrails, and the honest way to name the difference is not “safer.” It is where the bar sits. One approach reaches broadly and qualifies through the conversation. Ours won’t start one unless this contact has already given us something specific to open with — quieter by design, and on a book with thin history it declines plenty of people you might have wanted contacted.
What these guarantees don’t cover
Four limits worth having in front of you, because each one changes how you’d run it.
- A graduated workflow really does send. Every workflow starts in review mode: the loop runs and the message lands in the agent’s approval queue instead of the lead’s inbox, and that stays the default until an admin changes it. Once a workflow is graduated, its messages go out with nobody reading them first. Each automatic send carries a line saying it came from an AI assistant, not configurable per workflow. The trade is still a trade.
- Sending hours are your account’s, not necessarily the recipient’s. The window governing an automatic email is the one configured on the account, defaulting to 8am–8pm in the account’s own time zone. A recipient-local check runs in addition when that contact’s time zone is genuinely on file; when it isn’t, the check is recorded as skipped rather than quietly substituting your zone for theirs. Text is stricter: an unknown recipient zone is a hard refusal there, because the law measures that window in the recipient’s local time.
- Tag enrollment is your team’s decision, not the contact’s. When you aim Autopilot with an include tag, that tag is the basis it runs on — an explicit choice someone on your team made, recorded as such. It is not a consent record the contact created and should not be read as one.
- Selection discipline is not delivery proof. All of the above is about who gets written to; what the reporting can establish afterwards is a separate question, covered in how to audit what an AI follow-up tool really did.
How to turn it on without regretting it
The rollout matters more than the settings:
- Leave review mode on and run a full week. You are not testing whether it sends. You are reading what it would have said, to people you know, before anyone outside the office does.
- Start with one workflow, the narrowest you have. A workflow can be stricter than the account it lives in and never looser. Use that.
- Aim it with tags before you aim it at the whole book. A group you chose is a smaller blast radius than your whole database, and it makes week one’s drafts something you can actually evaluate.
- Read the refusals, not the send count. The reasons it declined tell you whether its judgment matches yours. The send count only tells you it was busy.
- Graduate one workflow at a time. A single workflow can go back into review without touching the others, so rollback is never all-or-nothing.
If week one produces drafts you would not have sent, the fix is not a better prompt. Those contacts did not have enough behind them.
Frequently asked questions
Will Ace Autopilot email someone my agent is already working?
No. If there has been an outbound touch from your side to that contact in the last seven days, Autopilot stays out, and no score, tier or estimated deal value overrides that. Where a message’s origin cannot be established exactly, it is treated as a human’s rather than assumed to be Autopilot’s own. A contact under contract is refused outright however long it has been.
Does Ace Autopilot need the contact’s consent?
It needs a consent basis and refuses when it cannot find one. Across your whole book that basis has to be evidenced: a real inbound message from them, a portal inquiry or registration they submitted themselves (including one with no message typed into it), closed business, or a first-party capture record. A passively viewed or saved property does not count. A contact with none of those is not selected automatically. When you aim Autopilot with an include tag instead, that enrollment is the basis, recorded as your team’s decision rather than as something the contact did. None of this is legal advice; your obligations depend on your channel and your state.
What does Ace Autopilot do when it has nothing specific to say?
Nothing, and it says why. A contact whose only signal is a property view, a score change or a modeled equity figure is declined rather than sent a generic note; those facts can influence timing but are removed before any draft exists. The refusal is recorded by name in that run’s log.
The one thing worth doing today
Take the two contacts from the top of this piece, the quiet buyer and the one under contract, and find out what your current follow-up automation would do with each of them tomorrow morning. Not what the vendor page says — what the tool would do with those two records. If you can’t answer that from a report, that is the finding.
What is the one contact in your database you would never want an automation to email, and how would a system know?
See what it would have said, before anyone else does
Autopilot is included with Ace Trove and starts in review mode: the full loop runs and the message lands in the agent’s queue, not the lead’s inbox. More on how it decides is on the Autopilot page, and team leads can start with Ace free inside Follow Up Boss.
Get Started Free